Semantika
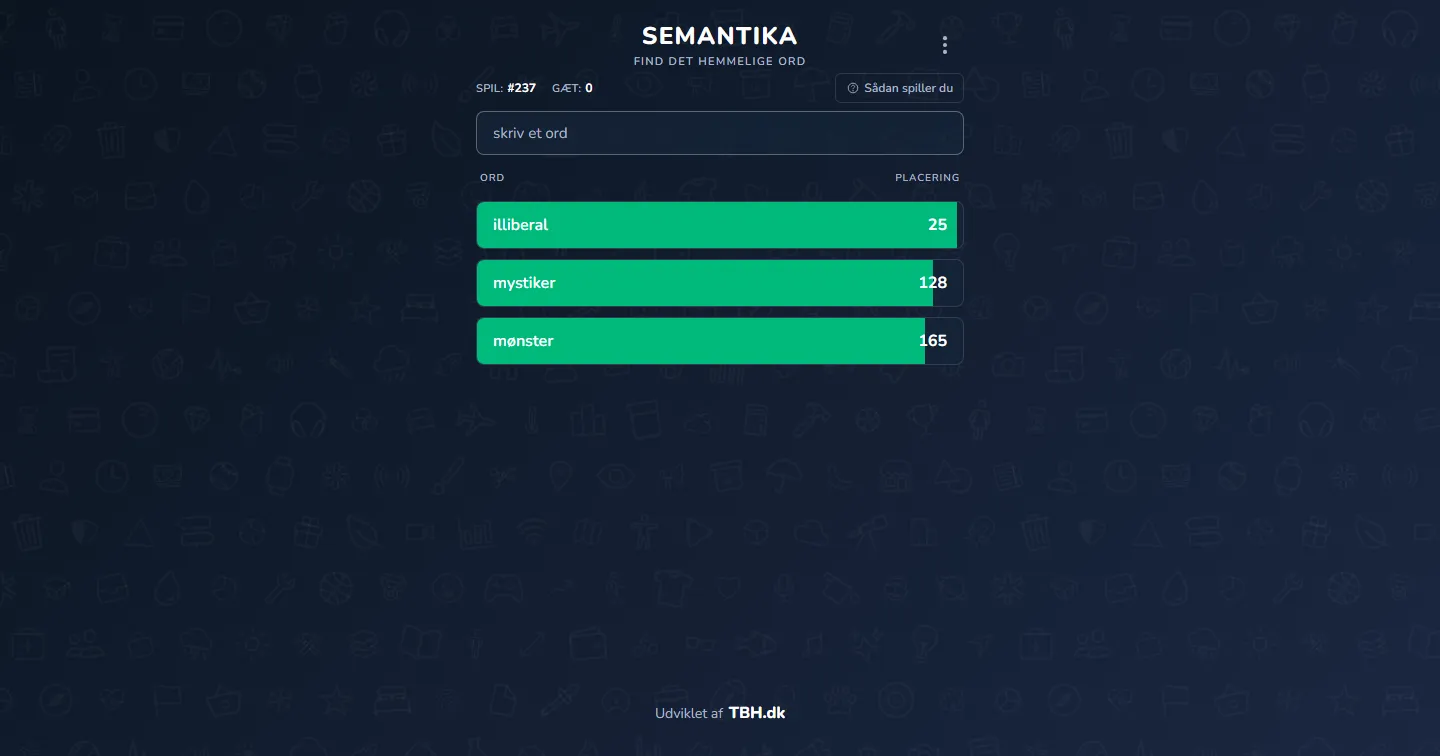
Semantika is a Danish word guessing game where you find the secret word by meaning instead of letters.
- Status
- Live
- Address
- semantika.dk
- Stack
- Next.js · TypeScript · Turso · Word2Vec
In numbers
- 88.502
- Guessable words
- 5.831
- Unique levels
- 1,4M
- Word vectors
How it works
Each guess gets a ranking. The secret word has ranking 1, and the lower the number, the closer you are. The ranking comes from cosine similarity between word vectors.
Example: the secret word is "kat" (cat)
The ranking reflects how often words appear in similar contexts in Danish texts, so it can differ from logical categories.
The AI model
Semantic similarity is calculated using a Danish Word2Vec model (DSL Skipgram 2020) trained on a large corpus of Danish texts from The Danish Language and Literature Society. The model converts each word into a 500-dimensional vector, where geometric proximity reflects semantic similarity.
The ranking uses a best-inflection strategy: each word is compared to the target in all its inflected forms (e.g. "rotte", "rotten", "rotter"), and the highest similarity decides the ranking. This catches meanings that the base form alone can miss.
Word lists
Guess vocabulary (~88,500 words)
Built from the DDO lemma list (The Danish Dictionary) and filtered with a blocklist that removes profanity and offensive or inappropriate words. Only words with a Word2Vec vector are included.
Target words / levels (5,831 words)
A subset filtered to nouns via DanNet. Words that are too abstract, controversial or obscure are removed.
Lemmatization
Inflected forms such as "katte", "katten" and "kattene" are normalized to the lemma "kat".
Design decisions
Turso over Supabase
Semantika's data is read-heavy: ~90,000 words with precomputed rankings. Turso (libSQL) runs edge replicas close to the user with sub-millisecond reads, and at our volume it is free. Supabase would give us more infrastructure than we use and slower cold starts.
Word2Vec over modern embeddings
Transformer-based models (BERT, GPT) produce context-dependent vectors: the same word may have different vectors in different sentences. Word2Vec gives one fixed vector per word and so the deterministic ranking the game is built on. DSL's Word2Vec model is also made for Danish and covers 1.4 million words.
Precomputed rankings
All rankings are precomputed and stored in the database, so a guess is a lookup instead of a cosine similarity calculation across 88,000 words (O(n)). The browser receives only the ranking for each guess.
Compound words
Danish is rich in compound words ("samarbejdsaftale" for "aftale"). Without adjustment, they would dominate the top of the ranking. The fix is a proportional penalty: compounds stay in the ranking but move down, so semantically relevant words come first.
Data sources
Technology
Try the game yourself
Play SemantikaNext project
Nordvec